Model comparison
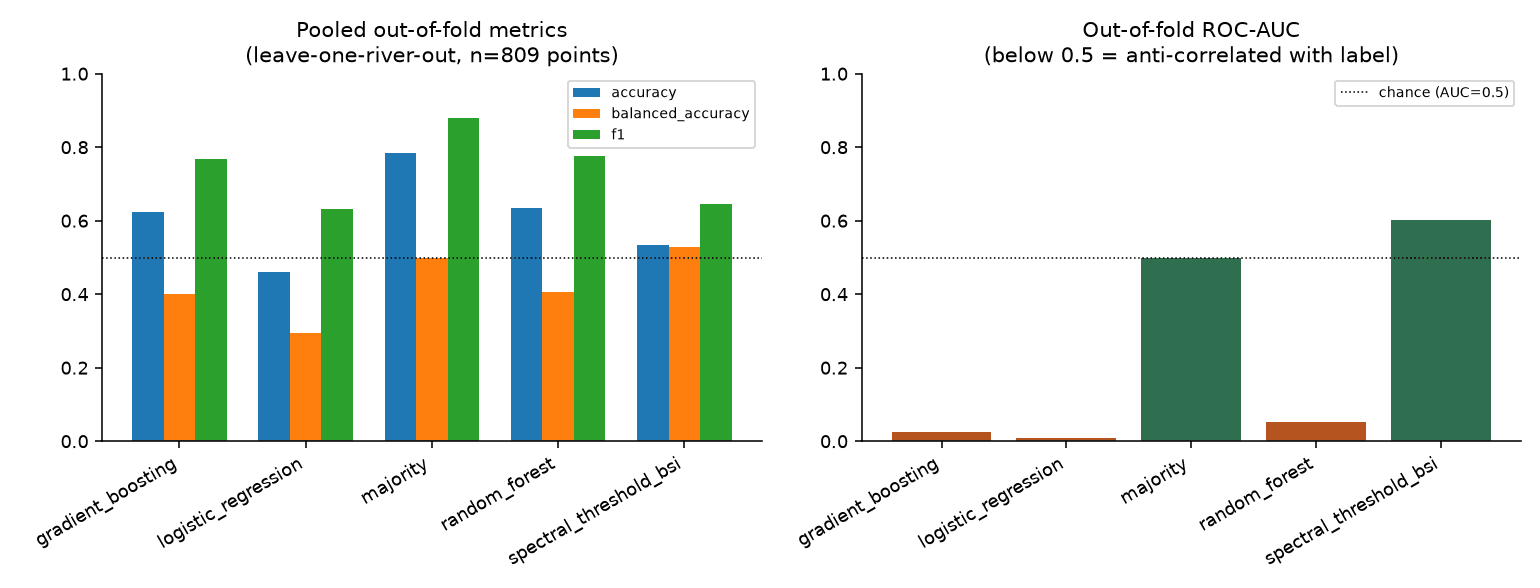
Five baselines evaluated under leave-one-river-out cross-validation: every held-out reach’s points are predicted by a model that never saw that reach during training.
Headline finding: the trained models fail to generalize — and this is robust
Out-of-fold ROC-AUC for logistic regression, random forest, and gradient boosting is 0.010–0.053 — far below the 0.5 chance level, meaning their predicted probabilities are anti-correlated with the true label once tested on a river reach they never trained on. This is not a data-leakage bug (the spatial split is structurally enforced and tested), and a reach-level bootstrap (see Uncertainty) confirms all three 95% CIs sit safely below 0.5. What it is not confirmed to be: a case where temporal differencing helps, or a fully isolated “reach fingerprint” mechanism — a feature-subset ablation below actually falsified that specific hypothesis, and a visual spot-check of real misclassified points found three distinct, unrelated causes (a snow-covered scene, a label-granularity issue, and one unexplained case) rather than one unifying story. A single-feature bare-soil-index threshold has a higher point estimate (AUC=0.604), but its bootstrap CI straddles 0.5 — that claim is not statistically robust at n=7 reaches. Full discussion in research/limitations.md.
| Model | Accuracy | Balanced accuracy | Precision | Recall | F1 | ROC-AUC |
|---|---|---|---|---|---|---|
| gradient_boosting | 0.625 | 0.400 | 0.746 | 0.794 | 0.769 | 0.026 |
| logistic_regression | 0.462 | 0.296 | 0.684 | 0.586 | 0.632 | 0.010 |
| majority | 0.786 | 0.500 | 0.786 | 1.000 | 0.880 | 0.500 |
| random_forest | 0.634 | 0.405 | 0.749 | 0.805 | 0.776 | 0.053 |
| spectral_threshold_bsi | 0.535 | 0.530 | 0.805 | 0.539 | 0.646 | 0.604 |
Pooled out-of-fold metrics across all 809 points (n per model). Per-fold precision/recall are not separately meaningful since each held-out reach carries a single true label — see Methods.
Feature-subset ablation: does temporal differencing help?
We expected temporal-difference features (recent minus baseline scene, ~6 years apart) to generalize better than absolute reflectance values, on the theory that absolute values encode reach- and season-specific characteristics a model could overfit to. The ablation below falsifies that: absolute-only features are consistently less bad than diff-only or the combined set, for every trained model.
| Model | absolute_only (AUC) | diff_only (AUC) | full (AUC) |
|---|---|---|---|
| gradient_boosting | 0.200 | 0.050 | 0.026 |
| logistic_regression | 0.443 | 0.020 | 0.010 |
| random_forest | 0.193 | 0.031 | 0.053 |
| spectral_threshold_bsi | 0.604 | — | 0.604 |
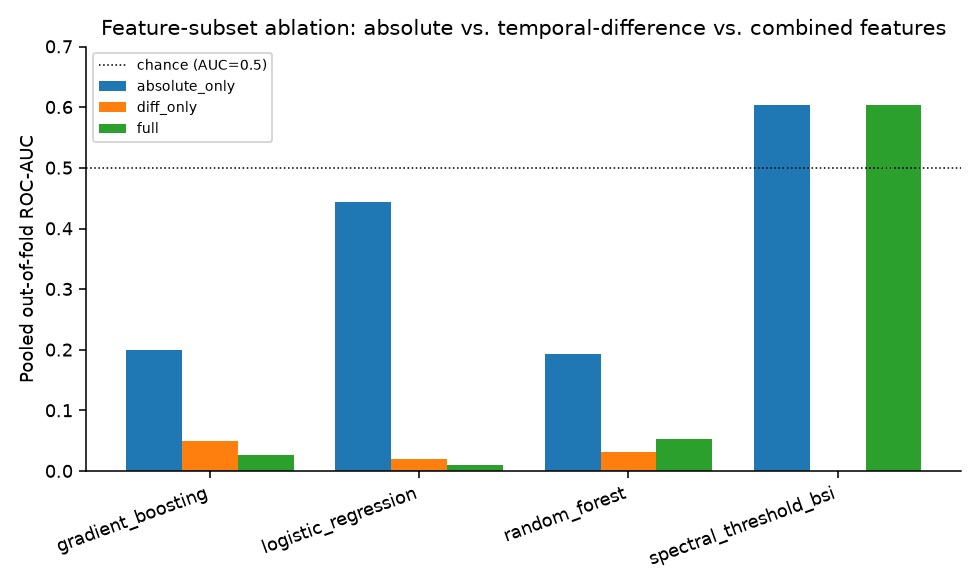
Best-supported reading: at n=6 training reaches per fold, an 8-dimensional feature space overfits faster than a 4-dimensional one — regardless of which physical quantity (absolute or differenced) it represents. See research/limitations.md for the full discussion.
Per-fold breakdown (accuracy)
| Model | Held-out reach | n | Accuracy |
|---|---|---|---|
| majority | yamuna_shamli_in | 146 | 1.000 |
| spectral_threshold_bsi | yamuna_shamli_in | 146 | 0.603 |
| logistic_regression | yamuna_shamli_in | 146 | 0.829 |
| random_forest | yamuna_shamli_in | 146 | 0.911 |
| gradient_boosting | yamuna_shamli_in | 146 | 0.925 |
| majority | krishna_vijayawada_in | 146 | 1.000 |
| spectral_threshold_bsi | krishna_vijayawada_in | 146 | 0.589 |
| logistic_regression | krishna_vijayawada_in | 146 | 0.582 |
| random_forest | krishna_vijayawada_in | 146 | 0.692 |
| gradient_boosting | krishna_vijayawada_in | 146 | 0.651 |
| majority | doodhganga_budgam_in | 150 | 1.000 |
| spectral_threshold_bsi | doodhganga_budgam_in | 150 | 0.360 |
| logistic_regression | doodhganga_budgam_in | 150 | 0.520 |
| random_forest | doodhganga_budgam_in | 150 | 0.880 |
| gradient_boosting | doodhganga_budgam_in | 150 | 0.953 |
| majority | mekong_chaudoc_vn | 44 | 1.000 |
| spectral_threshold_bsi | mekong_chaudoc_vn | 44 | 0.591 |
| logistic_regression | mekong_chaudoc_vn | 44 | 0.659 |
| random_forest | mekong_chaudoc_vn | 44 | 0.841 |
| gradient_boosting | mekong_chaudoc_vn | 44 | 0.727 |
| majority | benue_makurdi_ng | 150 | 1.000 |
| spectral_threshold_bsi | benue_makurdi_ng | 150 | 0.593 |
| logistic_regression | benue_makurdi_ng | 150 | 0.400 |
| random_forest | benue_makurdi_ng | 150 | 0.727 |
| gradient_boosting | benue_makurdi_ng | 150 | 0.667 |
| majority | kallada_kollam_in | 103 | 0.000 |
| spectral_threshold_bsi | kallada_kollam_in | 103 | 0.748 |
| logistic_regression | kallada_kollam_in | 103 | 0.010 |
| random_forest | kallada_kollam_in | 103 | 0.010 |
| gradient_boosting | kallada_kollam_in | 103 | 0.010 |
| majority | stcroix_grantsburg_us | 70 | 0.000 |
| spectral_threshold_bsi | stcroix_grantsburg_us | 70 | 0.186 |
| logistic_regression | stcroix_grantsburg_us | 70 | 0.000 |
| random_forest | stcroix_grantsburg_us | 70 | 0.000 |
| gradient_boosting | stcroix_grantsburg_us | 70 | 0.000 |